
In short: A private context platform connects a company's organisational structure, knowledge and operations and delivers that context to AI agents without the data leaving the customer's environment. In banking, insurance, healthcare, telecom and legal services, the evaluation starts from seven criteria: where the data and credentials live, when the permission is applied, whether every answer cites its source, how the platform models the company's structure, what audit trail it leaves, whether the data can become model training and whether the company can switch models without redoing the integration. At the end of the text there is a list of questions to take to the meeting with the vendor.
Enterprise AI agents depend on three kinds of context. Organisational structure says who is who, which departments exist and who owns each process. Knowledge gathers policies, contracts, procedures and decisions. Operations bring the current state of the business: orders, tickets, active contracts and indicators.
The private context platform connects these three kinds, organises the relationships between them and delivers to the agent only the passage the person asking is allowed to see. The word "private" describes where this happens: inside the company's own cloud or data centre.
Company Brain (the business's operational brain): the layer that connects a company's systems once, organises data, memory and knowledge, and delivers that context to any AI agent with each person's permissions.
Strattum's Company Brain is a private context platform. The examples below use its architecture to show how each criterion looks in practice.
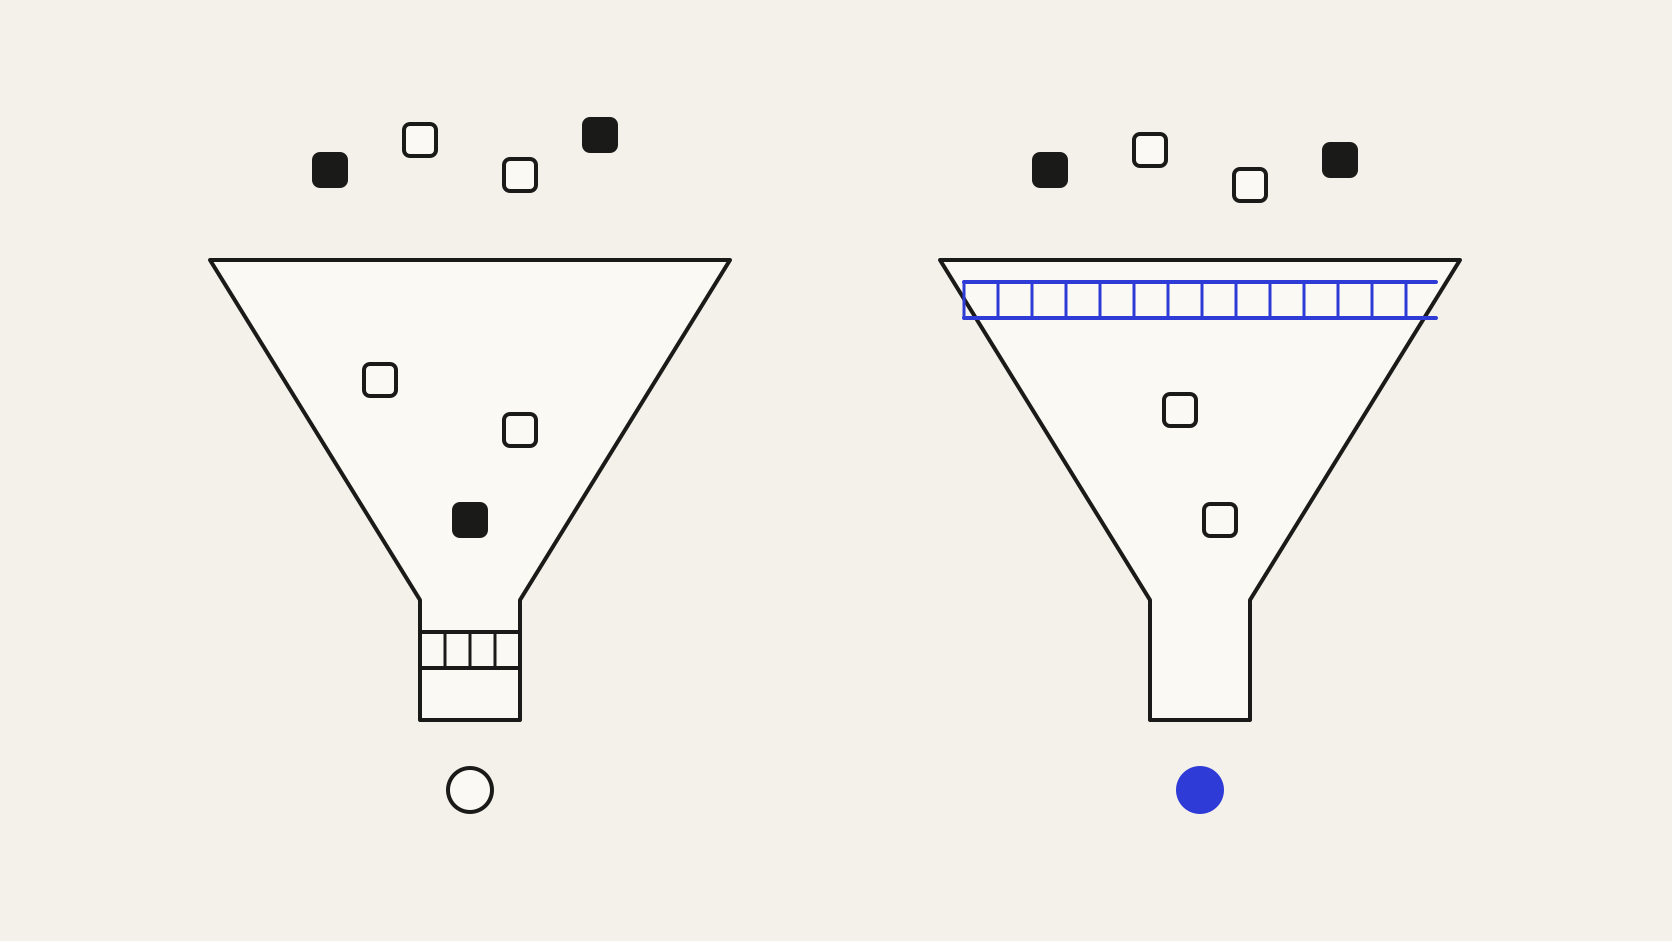
Brazil's data protection law (LGPD) requires the company to know who processes each piece of personal data, for what purpose and with which processors. Sector regulators and internal auditors add the question of how a decision was made and on the basis of which information. A platform that copies the data out of the tenant creates a new processor, and an answer without a source citation does not hold up in an audit. Both points weigh more than answer quality in the first round of evaluation.
The question has to go beyond "the data stays in Brazil". It is worth mapping where the records, the credentials for the sources, the encryption keys, the vector indexes and the logs live. Many platforms run a connector in the customer's cloud and process the rest in the vendor's environment. In that design, the private context is processed outside the tenant.
In the Company Brain, the whole platform runs in the customer's cloud, on AWS, Azure, GCP, OCI or on-premises. Records, credentials and secrets, encryption keys and network access stay in the company's tenant. The two models are compared in BYOC or hosted.
There are two ways to apply permissions. In the first, the platform retrieves the most relevant passages and then removes the ones the user may not see. In the second, the filter comes before ranking, and the forbidden passage is never retrieved. The first leaves gaps: the forbidden passage can influence the order of the results or appear in an intermediate log.
Another point is where the permission comes from. Platforms that mirror permissions in their own database fall out of date when someone moves to another team. The Company Brain uses the OAuth of the customer's tenant and applies ACL, classification and retention according to the customer's policy, with no mirroring.
An answer that is useful in an audit points to the document, the version and the passage it came from. Without the version, the auditor cannot tell whether the policy cited was the one in force on the date of the decision. In the Company Brain, every document comes in with metadata for source, version, author and classification, and every answer carries a citation anchored to the source paragraph. The topic is covered in detail in Source citation and audit are an architecture requirement.
In a private context platform, indexing documents solves part of the problem. To answer "which of this customer's contracts expire this quarter and who is responsible", the agent needs to know that Customer, Contract and Owner are entities linked across CRM, ERP and spreadsheets.
The Company Brain's Memory Graph starts from an ontology written in YAML and versioned in Git, reviewed in pull requests like code. The Memory Worker resolves the entities across systems and writes the relationships to the graph, without depending on a nightly load. The ontology is what makes the AI use the company's vocabulary, as Business ontology explains.
Three records support an AI audit: the log of every query, with who asked and what context they received; the lineage of each attribute back to its source; and the version history of the knowledge used. In the Company Brain, every query is logged and audited, and the lineage runs from the attribute at the source to the answer.
To organise the risk analysis, the NIST AI Risk Management Framework is a reference accepted by risk and compliance teams, and it helps turn these records into controls.
The contract has to state whether data sent to the model may be retained or used for training, by the platform vendor and by the model provider. The architecture matters too: when the context is assembled inside the tenant and only the passage needed goes on to the model, exposure goes down. At Strattum, customer data is never used to train models. The integration design that guarantees this is in Data that does not become training.
Models change every quarter. If the context is tied to one vendor's assistant, every switch means redoing the integration and revalidating permissions. An independent context layer delivers the same context to any model over MCP or API. With the context already organised, the company uses smaller models for most tasks and saves the larger ones for what really requires them, which cuts token consumption.
To evaluate the Company Brain against these criteria in your company's environment, talk to the Strattum team at strattum.ai/contato.
